
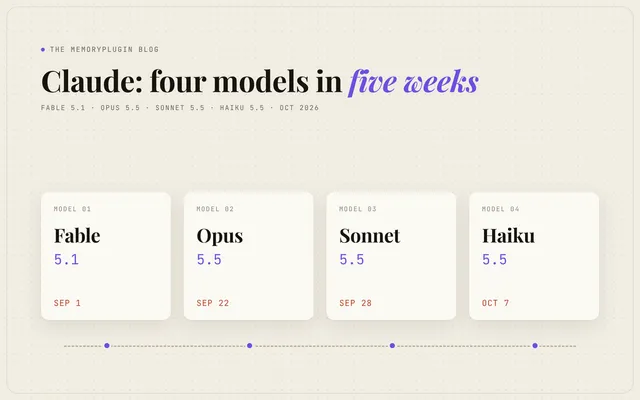
Quick answer: Anthropic shipped four Claude models in five weeks: Fable 5.1 (Sep 1), Opus 5.5 (Sep 22), Sonnet 5.5 (Sep 28) and Haiku 5.5 (Oct 7). It also raised five-hour limits, added a savable rate-limit reset, merged Cowork into every chat, and gave Max and Team monthly API credits. Developers love the price-to-performance; Cowork users miss the old layout.
What did Anthropic ship for Claude in September and October 2026?
Sources: the Claude release notes, the platform release notes and the model announcements.
| Feature | What it does | Who gets it | Date |
|---|---|---|---|
| Fable 5.1 / Mythos 5.1 | Top model. Mythos is the same model with looser safeguards | Fable: GA. Mythos: trusted-access only | Sep 1 |
| Cowork in every conversation | No mode switch between chat and agent tasks | Pro and Max, rolling out | Sep 16 |
| Design, Slides, Docs in any chat | Designs, decks and living docs inline | Every plan incl. Free (Enterprise: beta, off by default) | Sep 16 |
| Opus 5.5 | Fable 5.1-level on most work, 40% cheaper than Opus 5 | Paid plans | Sep 22 |
| Higher limits + saveable reset | Bigger five-hour limits, one reset you can save | Pro, Max, Team, seat-based Enterprise | Sep 22 |
| Sonnet 5.5 | 30%+ faster than Sonnet 5, up to 30% cheaper | All platforms | Sep 28 |
| Haiku 5.5 | Small model, 1M context, 128k output | API and clouds | Oct 7 |
| Monthly API credits | Max 5x $100, Max 20x $200, Team up to $500 pooled | Max and Team | Oct 7 |
Is Claude Opus 5.5 better than Fable 5.1?
Not quite. Anthropic says Opus 5.5 "performs at the level of Claude Fable 5.1 on most work and costs 40% less to run than Opus 5." It costs $4 per million input tokens and $20 per million output tokens, and output is more than 30% faster. Anthropic also improved the writing, which it calls "one of the most common areas of feedback" on Opus 5.
There are trade-offs. "Most cybersecurity tasks will be re-routed to Opus 4.8." It can't run with thinking off. It also launches with "preserved thinking," an anti-distillation measure that stops API users from editing earlier context to pull out the model's reasoning. That applies to API accounts created on or after August 31.
Should I use Sonnet 5.5 or Opus 5.5?
Anthropic pitches Sonnet 5.5 for "well-scoped everyday tasks, fixing bugs, and creating polished documents, slides, and spreadsheets," and Opus for "complex work requiring careful judgment." If you build on the API, read the migration notes first. With Sonnet, "thinking off" now means between_tools. Anthropic lists five breaking changes, including forced tool use now returning a 400 error.
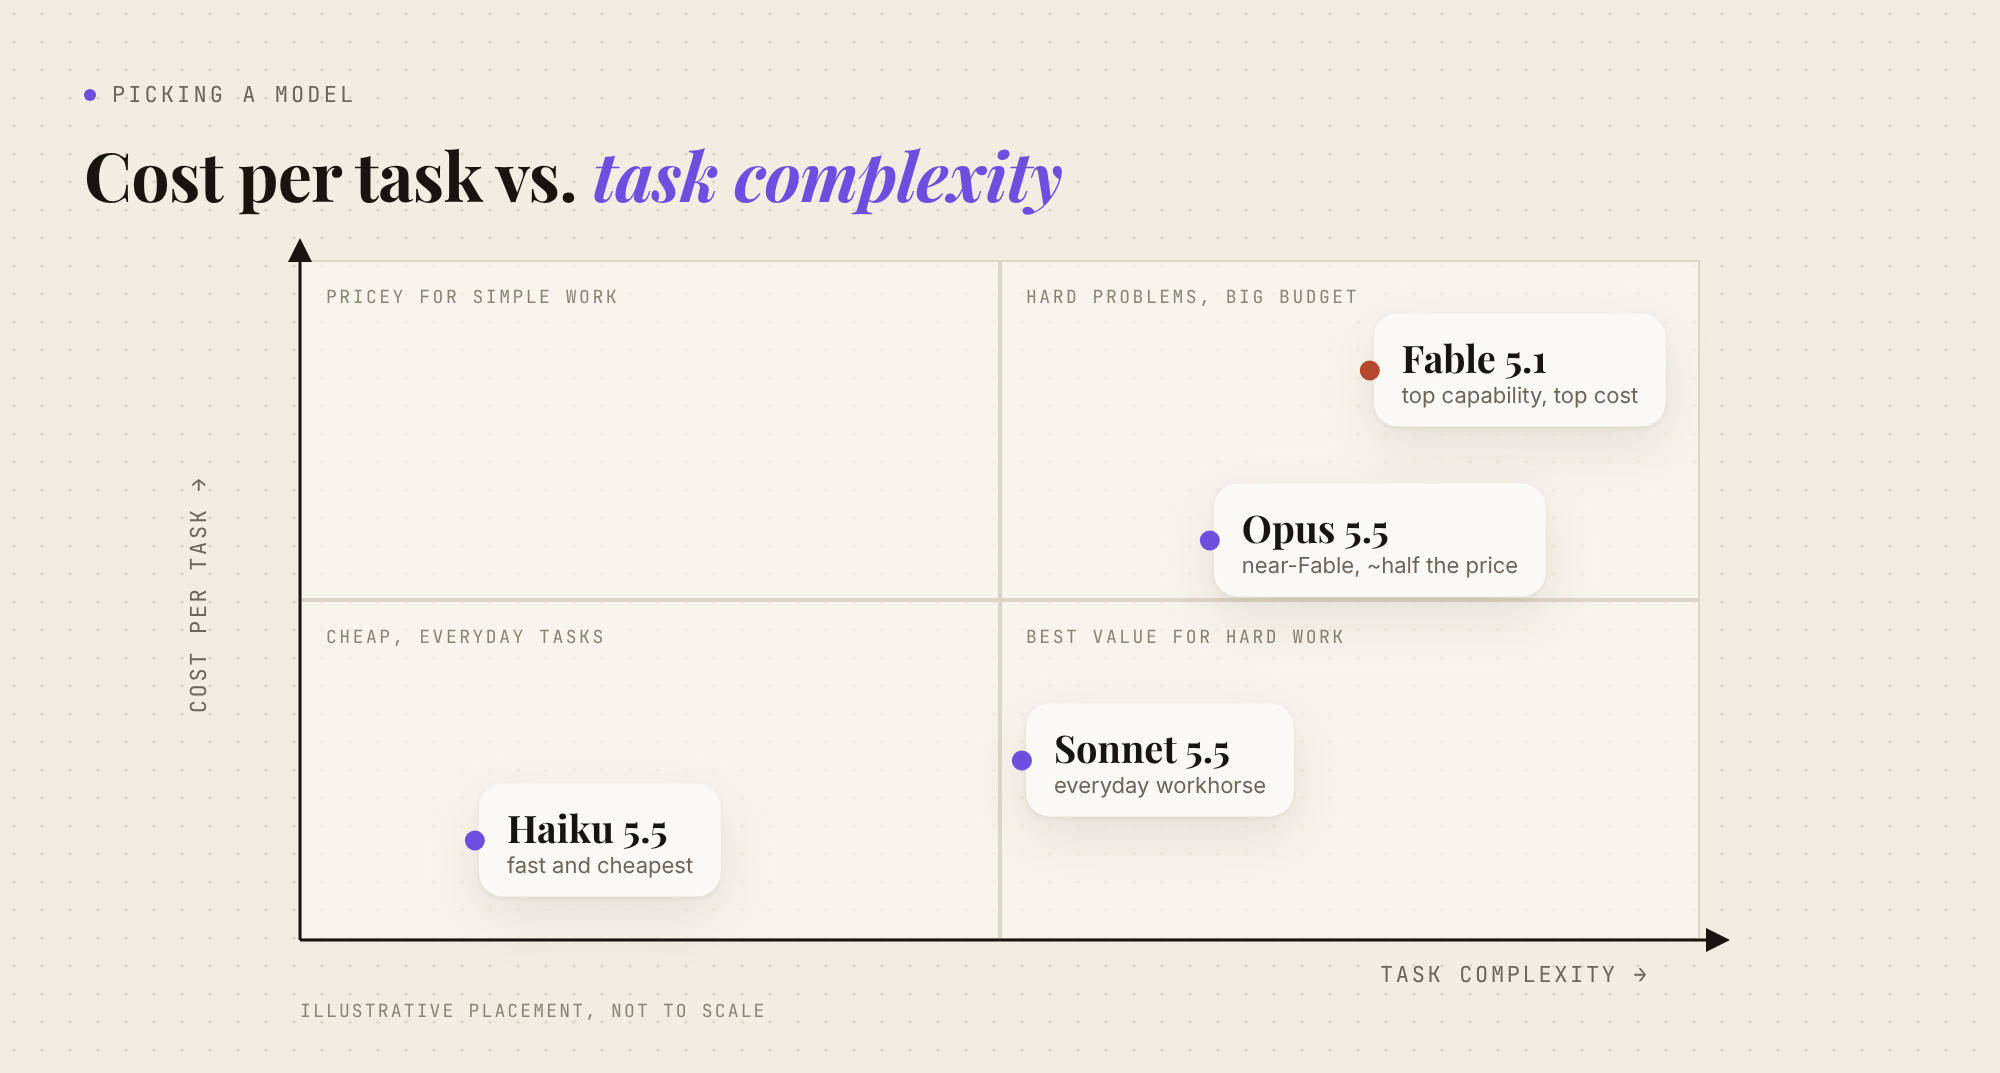
Anthropic's own figure for Opus 5.5 is 40% cheaper than Opus 5 (not half price). Haiku 5.5 brings a 1M-token context window and adaptive thinking to the small tier, and Anthropic is pitching it for computer use and browser use.
What changed in the Claude app itself?
Cowork and chat are now one Claude. Anthropic says "your chats, Cowork tasks, projects, connectors, and skills carry over." This builds on August 25, when memory started working across chat and Cowork.
The saveable reset is the quiet win. If you hit the five-hour limit on a slow day, you can keep the reset for a day when you need it.
What are people saying?
Love: the reset and the lineup.
"NO WAYYYY BANKED RESETS IN CLAUDE" (@fireboltdude)
"fleet coordinator model: opus 5.5 / code writer subagent: sonnet 5.5 / file search etc: haiku 5.5 / really complex features: fable 5.1" (@emmagine79)
@PawelHuryn's bug-fixing test scored Sonnet 5.5 (max) at 55.5 and GPT-6 Astra (max) at 45. That's one person's benchmark.
Complain: about speed and token use at max effort.
"Opus 5.5 on Max is still running, it's been 9 hours, and it has only done 2/3 tests." (@rohit3a)
"Sonnet 5.5 is cheaper and faster (on paper), but it used the most tokens." (@AdamDittrichOne)
So is the Claude 5.5 family worth switching to?
If you're on Opus 5, yes. Opus 5.5 is cheaper, faster and a better writer, and limits went up instead of down. If you run agents on the API, set aside time for the Sonnet 5.5 breaking changes and rerun your evals.
Anthropic keeps tying more to your Claude account: memory across chat and Cowork, and projects that carry over. That helps continuity inside Claude, but it does nothing when you switch to ChatGPT. I use MemoryPlugin to keep one memory across 23 AI platforms. Core is $89/year with a 7-day trial. Copilot and Meta AI aren't supported.